Note
Go to the end to download the full example code.
Temperature Scaling on MNIST
Temperature scaling divides every logit of a classifier by a single learned
scalar T > 0 before the softmax, q = softmax(z / T). With T > 1 the
predicted distribution is flattened, which counteracts the overconfidence of
over-trained networks; because all logits are divided by the same positive
number their ranking, and therefore the accuracy, stays unchanged. This example
over-trains a small MLP on an MNIST subset until it is overconfident, fits the
temperature on a held-out split by minimising the negative log-likelihood,
compares NLL, Brier score and expected calibration error before and after
calibration, draws the reliability diagram, and shows how the calibration-split
NLL depends on the temperature.
from __future__ import annotations

import matplotlib.pyplot as plt
import numpy as np
import torch
from torch import nn

from probly.calibrator import calibrate
from probly.metrics import expected_calibration_error
from probly.predictor import predict_raw
from probly.plot import PlotConfig
from probly.transformation.calibration import temperature_scaling
from probly_benchmark.data import load_mnist

from examples.utils.calibration import brier, nll, plot_reliability_diagram
from examples.utils.model import ResFFN
from examples.utils.plotting import plot_mnist_uncertainty

NUM_CLASSES = 10
RELIABILITY_BINS = 15
NUM_TRAIN = 4096
BATCH_SIZE = 256

config = PlotConfig()
BLUE, RED, GREEN = config.categorical_palette[:3]
Setup
Use a small subset of the training set to fit the network (so that over-training makes it overconfident – the regime where calibration helps), the first half of the test set as the calibration split, and the second half as the evaluation set.
train_loader, test_loader = load_mnist(batch_size=BATCH_SIZE)

X_train_batches, y_train_batches = zip(*train_loader)
X_train = torch.cat([x.view(-1, 28 * 28) for x in X_train_batches])[:NUM_TRAIN]
y_train = torch.cat(list(y_train_batches))[:NUM_TRAIN]

X_test_batches, y_test_batches = zip(*test_loader)
X_all = torch.cat([x.view(-1, 28 * 28) for x in X_test_batches])
y_all = torch.cat(list(y_test_batches))

half = len(X_all) // 2
X_calib, y_calib = X_all[:half], y_all[:half]
X_test, y_test = X_all[half:], y_all[half:]
Model
Over-train the MLP on the small subset until it fits it (near) perfectly, which makes its test-set probabilities overconfident.
torch.manual_seed(0)
model = ResFFN(in_features=28 * 28, hidden_features=256, out_features=NUM_CLASSES)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
criterion = nn.CrossEntropyLoss()

model.train()
for _epoch in range(30):
    perm = torch.randperm(len(X_train))
    for start in range(0, len(X_train), BATCH_SIZE):
        idx = perm[start : start + BATCH_SIZE]
        opt.zero_grad()
        loss = criterion(model(X_train[idx]), y_train[idx])
        loss.backward()
        opt.step()
model.eval()
ResFFN(
  (first): Linear(in_features=784, out_features=256, bias=True)
  (layers): ModuleList(
    (0-11): 12 x ResFFNLayer(
      (linear): Linear(in_features=256, out_features=256, bias=True)
      (norm): LayerNorm((256,), eps=1e-05, elementwise_affine=True)
      (relu): ReLU()
    )
  )
  (last): Linear(in_features=256, out_features=10, bias=True)
)
Calibrate
Wrap the model and fit the temperature on the calibration split. The wrapper is itself a logit classifier, so it can be used wherever the original model was.
Fitted temperature: T = 2.022
Evaluation
Compare negative log-likelihood (NLL), Brier score, and the expected calibration
error (probly.metrics.expected_calibration_error(), the metric used in the
temperature scaling paper) before and after calibration. The accuracy is the same
for both models.
labels_test = y_test.numpy()
with torch.no_grad():
    uncal_probs = model(X_test).softmax(-1).numpy()
    cal_probs = predict_raw(calibrated_model, X_test).softmax(-1).numpy()

uncal_ece = float(expected_calibration_error(uncal_probs, labels_test, num_bins=RELIABILITY_BINS))
cal_ece = float(expected_calibration_error(cal_probs, labels_test, num_bins=RELIABILITY_BINS))

print(f"Accuracy (uncalibrated): {(uncal_probs.argmax(-1) == labels_test).mean() * 100:.1f}%")
print(f"Accuracy (calibrated):   {(cal_probs.argmax(-1) == labels_test).mean() * 100:.1f}%")
print(f"Uncalibrated:  NLL={nll(uncal_probs, labels_test):.4f}  Brier={brier(uncal_probs, labels_test):.4f}  ECE={uncal_ece:.4f}")
print(f"Temperature:   NLL={nll(cal_probs, labels_test):.4f}  Brier={brier(cal_probs, labels_test):.4f}  ECE={cal_ece:.4f}")
Accuracy (uncalibrated): 96.8%
Accuracy (calibrated):   96.8%
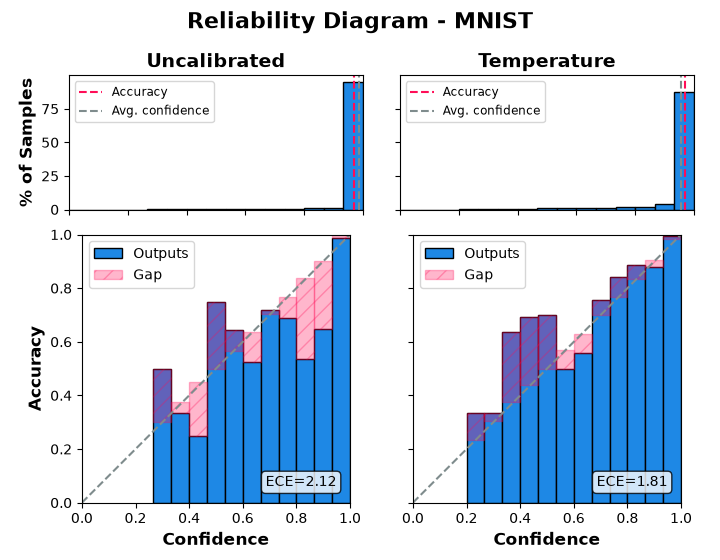
Uncalibrated:  NLL=0.1645  Brier=0.0558  ECE=0.0212
Temperature:   NLL=0.1273  Brier=0.0528  ECE=0.0181
Reliability Diagram
The top row shows the share of test predictions per confidence bin, with the accuracy and the average confidence marked; the bottom row shows the accuracy of each bin (“Outputs”) and its gap to the bin’s mean confidence (“Gap”), in the style of [GPSW17]. Empty bins are left out, and bins with only a handful of predictions (see the histogram) are noisy. The uncalibrated model’s bars sit below the diagonal (overconfident); temperature scaling moves them toward it.
plot_reliability_diagram(
    {
        "Uncalibrated": uncal_probs,
        "Temperature": cal_probs,
    },
    labels_test,
    title="Reliability Diagram - MNIST",
    n_bins=RELIABILITY_BINS,
)
plt.show()
findfont: Failed to find font weight 300 for DejaVu Sans, now using 400.
findfont: Failed to find font weight 600 for DejaVu Sans, now using 700.
findfont: Failed to find font weight 300 for DejaVu Sans, now using 400.
The Learned Temperature
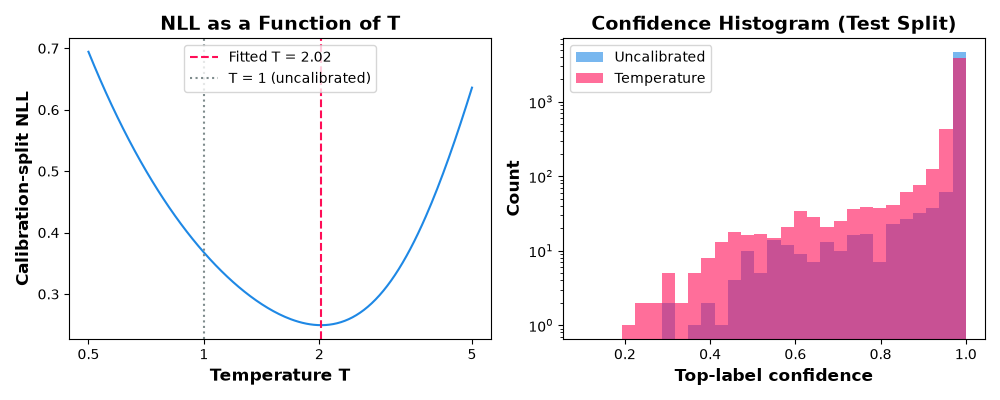
Temperature scaling has a single parameter, so its whole fitting problem can be
drawn: the left panel shows the NLL on the calibration split as a function of
T, and the fitted value sits at its minimum. The right panel shows what the
fitted T does to the predictions. It pulls the top-label confidence away
from 1, where the over-trained model had piled up most of its mass.
with torch.no_grad():
    calib_logits = model(X_calib)
temperatures = np.geomspace(0.5, 5.0, 200)
calib_nll = [float(nn.functional.cross_entropy(calib_logits / t, y_calib)) for t in temperatures]

fig, (ax_nll, ax_hist) = plt.subplots(1, 2, figsize=(10, 4))
ax_nll.plot(temperatures, calib_nll, color=BLUE)
ax_nll.axvline(temperature, color=RED, linestyle="--", label=f"Fitted T = {temperature:.2f}")
ax_nll.axvline(1.0, color=config.color_neutral, linestyle=":", label="T = 1 (uncalibrated)")
ax_nll.set_xscale("log")
ax_nll.set_xticks([0.5, 1, 2, 5], labels=["0.5", "1", "2", "5"])
ax_nll.minorticks_off()
ax_nll.set_xlabel("Temperature T")
ax_nll.set_ylabel("Calibration-split NLL")
ax_nll.set_title("NLL as a Function of T")
ax_nll.legend()

bins = np.linspace(1.0 / NUM_CLASSES, 1.0, 30)
ax_hist.hist(uncal_probs.max(-1), bins=bins, alpha=config.histogram_alpha, color=BLUE, label="Uncalibrated")
ax_hist.hist(cal_probs.max(-1), bins=bins, alpha=config.histogram_alpha, color=RED, label="Temperature")
ax_hist.set_yscale("log")
ax_hist.set_xlabel("Top-label confidence")
ax_hist.set_ylabel("Count")
ax_hist.set_title("Confidence Histogram (Test Split)")
ax_hist.legend(loc="upper left")
fig.tight_layout()

plt.show()
findfont: Failed to find font weight 300 for DejaVu Sans, now using 400.
findfont: Failed to find font weight 300 for STIXGeneral, now using 400.
findfont: Failed to find font weight 300 for STIXGeneral, now using 400.
findfont: Failed to find font weight 300 for STIXNonUnicode, now using 400.
findfont: Failed to find font weight 300 for STIXNonUnicode, now using 400.
findfont: Failed to find font weight 300 for STIXSizeOneSym, now using 400.
findfont: Failed to find font weight 300 for STIXSizeTwoSym, now using 400.
findfont: Failed to find font weight 300 for STIXSizeThreeSym, now using 400.
findfont: Failed to find font weight 300 for STIXSizeFourSym, now using 400.
findfont: Failed to find font weight 300 for STIXSizeFiveSym, now using 400.
findfont: Failed to find font weight 300 for cmmi10, now using 400.
findfont: Failed to find font weight 300 for cmsy10, now using 400.
findfont: Failed to find font weight 300 for cmr10, now using 400.
findfont: Failed to find font weight 300 for cmtt10, now using 400.
findfont: Failed to find font weight 300 for cmti10, now using 400.
findfont: Failed to find font weight 300 for cmb10, now using 400.
findfont: Failed to find font weight 300 for cmss10, now using 400.
findfont: Failed to find font weight 300 for cmex10, now using 400.
findfont: Failed to find font weight 300 for DejaVu Sans, now using 400.
findfont: Failed to find font weight 300 for DejaVu Sans, now using 400.
findfont: Failed to find font weight 300 for DejaVu Sans Mono, now using 400.
findfont: Failed to find font weight 300 for DejaVu Sans Display, now using 400.
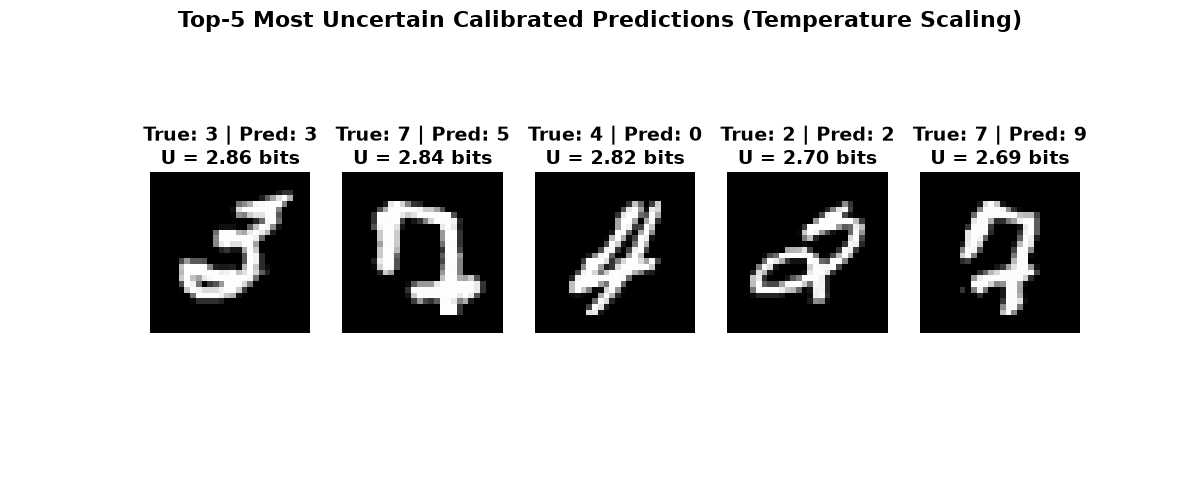
Most Uncertain Calibrated Predictions
images_test = (X_test.view(-1, 28, 28) * 255).byte()
entropy_bits = -(cal_probs * np.log2(np.clip(cal_probs, 1e-12, 1.0))).sum(-1)

plot = plot_mnist_uncertainty(
    images_test,
    y_test,
    entropy_bits,
    cal_probs,
    title="Top-5 Most Uncertain Calibrated Predictions (Temperature Scaling)",
)
plot.show()
Total running time of the script: (0 minutes 21.437 seconds)