Note
Go to the end to download the full example code.
Active Learning with sklearn - Margin vs Random
Compare margin sampling against random query selection on the Digits
dataset using a bare LogisticRegression.
No wrapper class is needed: sklearn classifiers already implement
fit, predict, and predict_proba, which is all the
Estimator protocol requires.
The workflow is:
Create an active learning pool with
from_dataset().Pick a query strategy (
MarginSamplingorRandomQuery).Iterate with
active_learning_steps().Evaluate with
compute_accuracy(),compute_ece(), andcompute_nauc().
from __future__ import annotations

import matplotlib.pyplot as plt
from sklearn.datasets import load_digits
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split

from probly.evaluation.active_learning import (
    MarginSampling,
    RandomQuery,
    active_learning_steps,
    compute_accuracy,
    compute_ece,
    compute_nauc,
    from_dataset,
)

SEED = 42
INITIAL_SIZE = 30
QUERY_SIZE = 30
N_ITERATIONS = 15
Data preparation
Load the Digits dataset (1797 samples, 64 features, 10 classes) and split into 80 % train / 20 % test. We start with only 30 labeled samples to make the advantage of informed query selection clearly visible.
X, y = load_digits(return_X_y=True)
x_train, x_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=SEED,
)
Run active learning
We run two strategies side by side: margin sampling (queries samples where
the model is most confused between its top two class predictions) and
random selection (baseline). A bare LogisticRegression is used directly
as the estimator – no wrapper needed.
strategies = {
    "Margin Sampling": MarginSampling(),
    "Random": RandomQuery(seed=SEED),
}

results: dict[str, dict] = {}

for name, strategy in strategies.items():
    pool = from_dataset(
        x_train, y_train, x_test, y_test, initial_size=INITIAL_SIZE, seed=SEED,
    )
    estimator = LogisticRegression(max_iter=1000, random_state=SEED)

    accuracies: list[float] = []
    eces: list[float] = []
    labeled_sizes: list[int] = []

    for state in active_learning_steps(
        pool, estimator, strategy, query_size=QUERY_SIZE, n_iterations=N_ITERATIONS,
    ):
        preds = state.estimator.predict(state.pool.x_test)
        probs = state.estimator.predict_proba(state.pool.x_test)
        accuracies.append(compute_accuracy(preds, state.pool.y_test))
        eces.append(compute_ece(probs, state.pool.y_test))
        labeled_sizes.append(state.pool.n_labeled)

    # NAUC (normalized area under the accuracy curve) summarizes how quickly
    # a strategy reaches good accuracy. Higher is better.
    nauc = compute_nauc(accuracies)
    results[name] = {
        "accuracies": accuracies,
        "eces": eces,
        "labeled_sizes": labeled_sizes,
    }
    print(f"{name:20s}  final acc: {accuracies[-1]:.3f}  ECE: {eces[-1]:.3f}  NAUC: {nauc:.3f}")
/home/runner/work/probly/probly/.venv/lib/python3.13/site-packages/sklearn/linear_model/_logistic.py:406: ConvergenceWarning: lbfgs failed to converge after 1000 iteration(s) (status=1):
STOP: TOTAL NO. OF ITERATIONS REACHED LIMIT

Increase the number of iterations to improve the convergence (max_iter=1000).
You might also want to scale the data as shown in:
    https://scikit-learn.org/stable/modules/preprocessing.html
Please also refer to the documentation for alternative solver options:
    https://scikit-learn.org/stable/modules/linear_model.html#logistic-regression
  n_iter_i = _check_optimize_result(
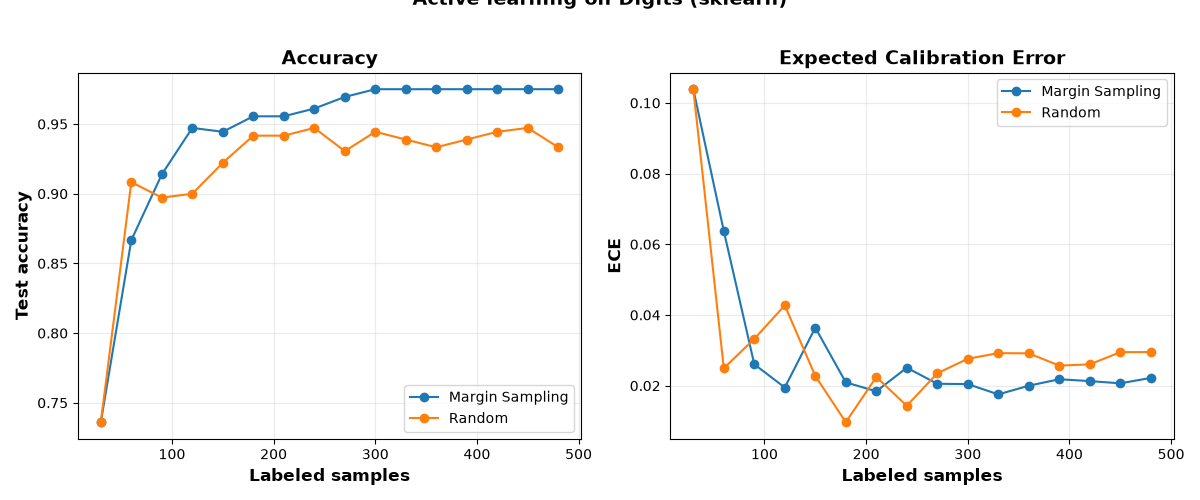
Margin Sampling       final acc: 0.975  ECE: 0.018  NAUC: 0.944
Random                final acc: 0.933  ECE: 0.030  NAUC: 0.925
Plot accuracy and calibration
Margin sampling reaches higher accuracy faster because it queries the samples the model is most confused about. The ECE (expected calibration error) panel shows how well-calibrated the predictions are at each step.
fig, (ax_acc, ax_ece) = plt.subplots(1, 2, figsize=(12, 5))

for name, data in results.items():
    ax_acc.plot(data["labeled_sizes"], data["accuracies"], marker="o", label=name)
    ax_ece.plot(data["labeled_sizes"], data["eces"], marker="o", label=name)

ax_acc.set_xlabel("Labeled samples")
ax_acc.set_ylabel("Test accuracy")
ax_acc.set_title("Accuracy")
ax_acc.legend()
ax_acc.grid(alpha=0.25)

ax_ece.set_xlabel("Labeled samples")
ax_ece.set_ylabel("ECE")
ax_ece.set_title("Expected Calibration Error")
ax_ece.legend()
ax_ece.grid(alpha=0.25)

fig.suptitle("Active learning on Digits (sklearn)", fontsize=14, y=1.02)
plt.tight_layout()
plt.show()
findfont: Failed to find font weight 300 for DejaVu Sans, now using 400.
findfont: Failed to find font weight 600 for DejaVu Sans, now using 700.
Next steps
This example uses MarginSampling
which only needs predict_proba. For richer strategies:
UncertaintyQuerydelegates scoring to the estimator’suncertainty_scoresmethod, letting you plug in any UQ measure (entropy, mutual information, etc.). Implement theUncertaintyEstimatorprotocol.BADGEQueryselects diverse uncertain batches using gradient embeddings. Implement theBadgeEstimatorprotocol to provide penultimate-layer features.
Combine these with probly’s UQ transformations (dropout, ensemble, evidential) for better uncertainty estimates in the active learning loop.
Total running time of the script: (0 minutes 1.692 seconds)