Note
Go to the end to download the full example code.
Uncertainty for Hugging Face vision transformers
The transformers integration is modality-agnostic: vision models like ViT
inherit from the same PreTrainedModel base and expose logits, so MC
dropout works on them exactly like on text models.
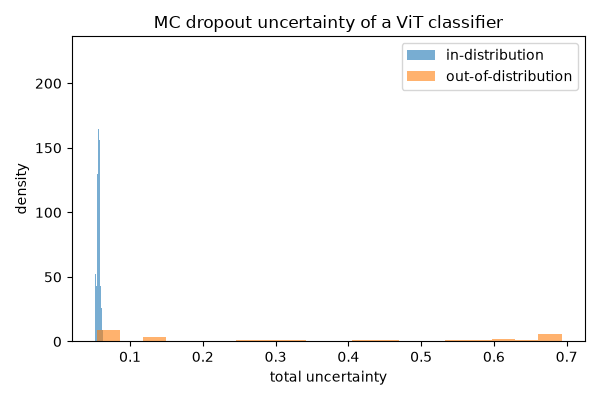
This example builds a tiny ViT classifier from a config (no downloads), trains it to separate images by where their bright region is, and shows that MC dropout assigns higher uncertainty to out-of-distribution noise images.
from __future__ import annotations

import matplotlib.pyplot as plt
import torch
from torch import nn
from transformers import ViTConfig, ViTForImageClassification

from probly.method import dropout
from probly.quantification import quantify
from probly.representer import representer

torch.manual_seed(0)
<torch._C.Generator object at 0x7f9b61b035d0>
Data
Class 0 images are bright in the top half, class 1 in the bottom half. Out-of-distribution images are pure high-variance noise.
def make_images(kind: str, n: int) -> torch.Tensor:
    images = torch.randn(n, 3, 16, 16) * 0.3
    if kind == "top":
        images[:, :, :8, :] += 1.0
    elif kind == "bottom":
        images[:, :, 8:, :] += 1.0
    elif kind == "noise":
        images = torch.randn(n, 3, 16, 16) * 1.5
    return images


X_train = torch.cat([make_images("top", 200), make_images("bottom", 200)])
y_train = torch.cat([torch.zeros(200, dtype=torch.long), torch.ones(200, dtype=torch.long)])
X_test = torch.cat([make_images("top", 100), make_images("bottom", 100)])
X_ood = make_images("noise", 100)
Model
A tiny ViT built from a config, wrapped with MC dropout and trained directly.
config = ViTConfig(
    image_size=16,
    patch_size=4,
    num_channels=3,
    hidden_size=32,
    num_hidden_layers=2,
    num_attention_heads=2,
    intermediate_size=64,
)
config.num_labels = 2

dropout_model = dropout(ViTForImageClassification(config), p=0.1, predictor_type="logit_classifier")

opt = torch.optim.AdamW(dropout_model.parameters(), lr=1e-3)
dropout_model.train()
for _epoch in range(120):
    opt.zero_grad()
    loss = nn.functional.cross_entropy(dropout_model(X_train).logits, y_train)
    loss.backward()
    opt.step()
dropout_model.eval()
ViTForImageClassification(
  (vit): ViTModel(
    (embeddings): ViTEmbeddings(
      (patch_embeddings): ViTPatchEmbeddings(
        (projection): Conv2d(3, 32, kernel_size=(4, 4), stride=(4, 4))
      )
      (dropout): Dropout(p=0.0, inplace=False)
    )
    (encoder): ViTEncoder(
      (layer): ModuleList(
        (0-1): 2 x ViTLayer(
          (attention): ViTAttention(
            (attention): ViTSelfAttention(
              (query): Sequential(
                (0): Dropout(p=0.1, inplace=False)
                (1): Linear(in_features=32, out_features=32, bias=True)
              )
              (key): Sequential(
                (0): Dropout(p=0.1, inplace=False)
                (1): Linear(in_features=32, out_features=32, bias=True)
              )
              (value): Sequential(
                (0): Dropout(p=0.1, inplace=False)
                (1): Linear(in_features=32, out_features=32, bias=True)
              )
            )
            (output): ViTSelfOutput(
              (dense): Sequential(
                (0): Dropout(p=0.1, inplace=False)
                (1): Linear(in_features=32, out_features=32, bias=True)
              )
              (dropout): Dropout(p=0.0, inplace=False)
            )
          )
          (intermediate): ViTIntermediate(
            (dense): Sequential(
              (0): Dropout(p=0.1, inplace=False)
              (1): Linear(in_features=32, out_features=64, bias=True)
            )
            (intermediate_act_fn): GELUActivation()
          )
          (output): ViTOutput(
            (dense): Sequential(
              (0): Dropout(p=0.1, inplace=False)
              (1): Linear(in_features=64, out_features=32, bias=True)
            )
            (dropout): Dropout(p=0.0, inplace=False)
          )
          (layernorm_before): LayerNorm((32,), eps=1e-12, elementwise_affine=True)
          (layernorm_after): LayerNorm((32,), eps=1e-12, elementwise_affine=True)
        )
      )
    )
    (layernorm): LayerNorm((32,), eps=1e-12, elementwise_affine=True)
  )
  (classifier): Sequential(
    (0): Dropout(p=0.1, inplace=False)
    (1): Linear(in_features=32, out_features=2, bias=True)
  )
)
Uncertainty on in-distribution vs out-of-distribution images
rep = representer(dropout_model, num_samples=50)
with torch.no_grad():
    uncertainty_id = quantify(rep.represent(X_test))["total"]
    uncertainty_ood = quantify(rep.represent(X_ood))["total"]

fig, ax = plt.subplots(figsize=(6, 4))
ax.hist(uncertainty_id.numpy(), bins=20, alpha=0.6, label="in-distribution", density=True)
ax.hist(uncertainty_ood.numpy(), bins=20, alpha=0.6, label="out-of-distribution", density=True)
ax.set_xlabel("total uncertainty")
ax.set_ylabel("density")
ax.set_title("MC dropout uncertainty of a ViT classifier")
ax.legend()
fig.tight_layout()
plt.show()
Total running time of the script: (0 minutes 16.958 seconds)